HANA News Blog

HANA Sequences - the hidden handbrake in the system

Matthias Sander • 31. August 2023

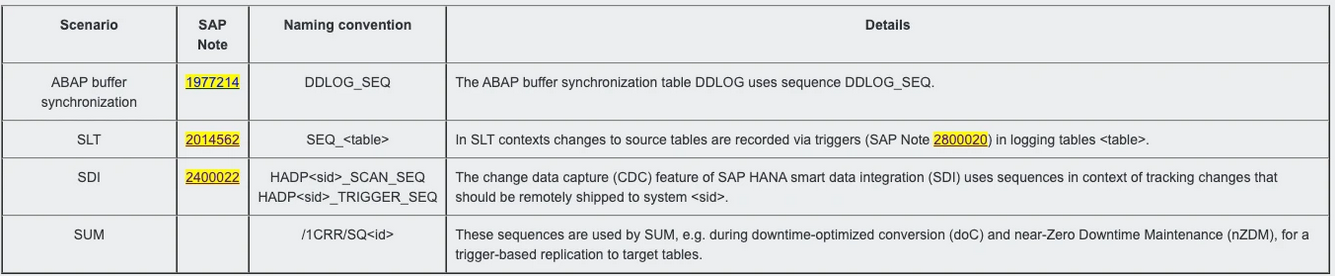
Usage of Sequences

Do you use sequences in your SAP HANA systems? This should definitely be checked. If not set up correctly, these can have a major impact on the performance of individual SQL statements. A HANA sequence can be compared with a consecutive number range in ABAP. The sequence generates unique, preceding numbers, which e.g. B. can be used by a HANA trigger or when INSERT into a table. Similar to ABAP, numbers can be buffered. By default, however, the cache is set to 1.


 If many operations access the sequence at the same time, there is a waiting situation until the next number is assigned. This problem can be solved by increasing the sequence cache. Note: There may be gaps in the assignment due to the use of the cache, but the numbers are always consecutive.


How do I check whether developers or even third-party vendors are using HANA sequences?
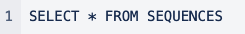

Recognize sequences in statements:


The sequence can be recognized in the statement by the “.NEXTVAL” function.
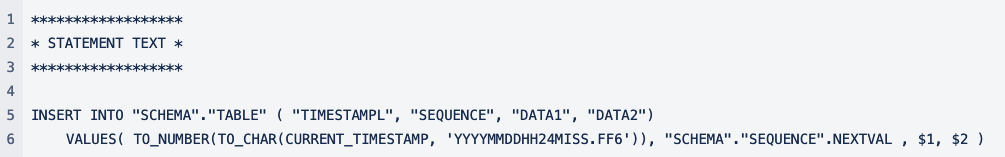
Example with triggers:


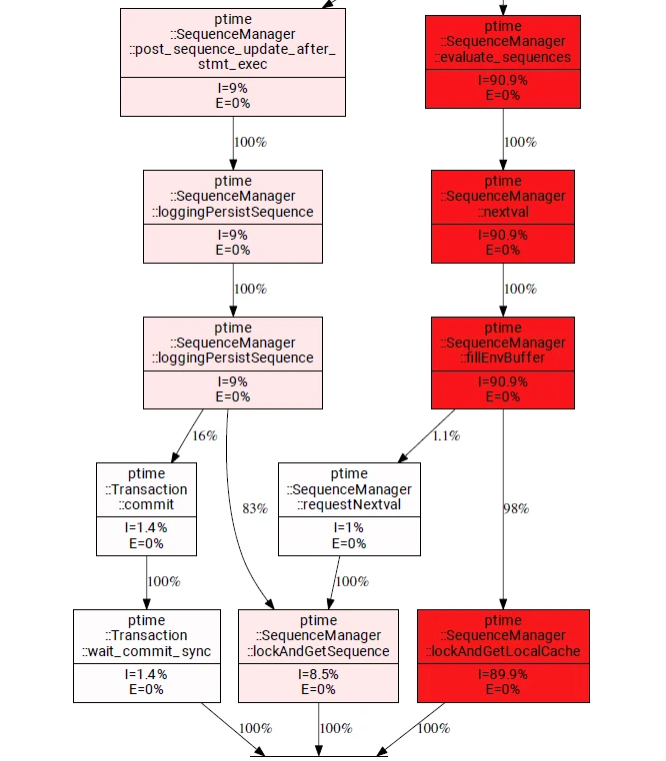
The trigger, which in turn uses a sequence, accounts for about 90% of the statement's runtime. Seen here in the context of the child processes.
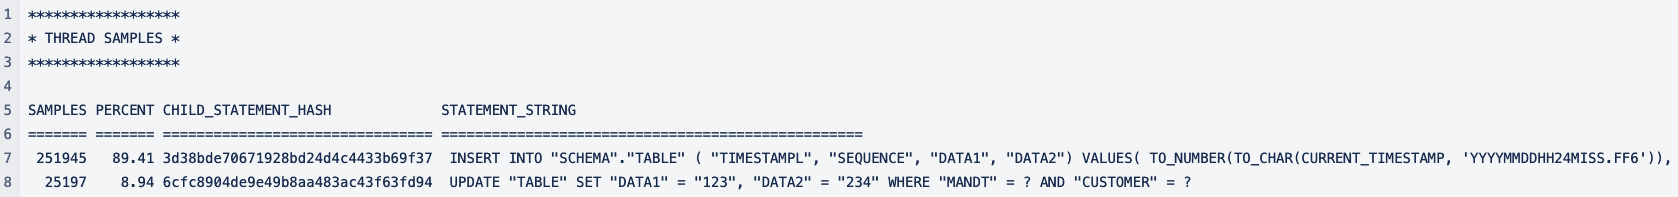
Kernel Profiler

Statement Collector of the trigger statement
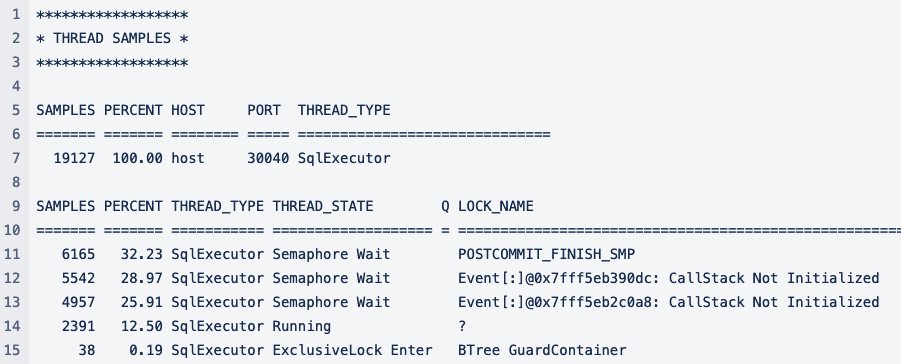
CallStack Not Initialized   : This is a generic, unspecific semaphore name used for various semaphores in IBM on Power environments. On Intel they follow the naming convention "<module>.cpp: <function>" instead, e.g. "DeltaIndexManager.cpp: TRexAPI::DeltaIndexManager::MergeAttributeThread::MergeAttributeThread".

The Kernel Profiler can be used to determine exactly what the DB is doing in this status. This also applies to other cases.
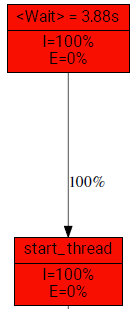
3,88s waiting

The HANA sequence accounts for over 90% of this

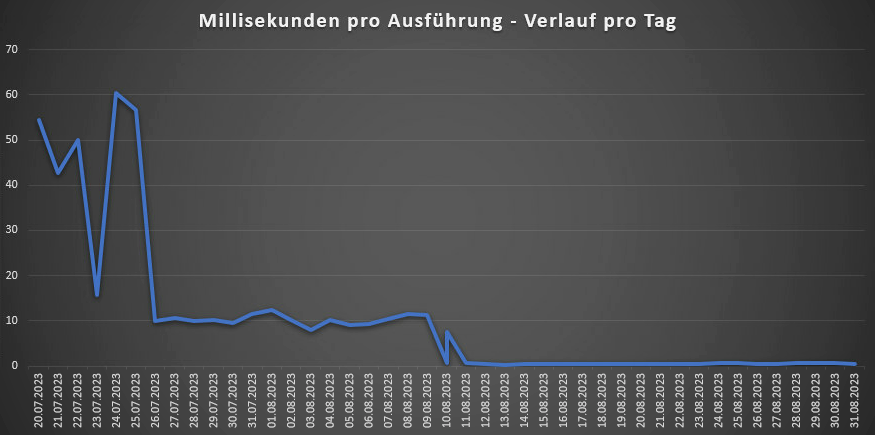
In the specific customer case, this had the following effect:

Peak times before caching: 160ms per execution

Peak times after caching: 1ms per execution


The daily average is as follows:

SAP HANA News by XLC
von Jens Gleichmann • 27. Oktober 2026
The topic of HANA performance is one of the most discussed topics in nearly every single SAP project we are involved. Performance has always been an important aspect in general; however, particularly when switching databases or application releases - whether moving from anyDB to HANA or, more specifically, from ERP on
Orientation in DMO scenarios
von Dominik Fiedler • 21. Oktober 2026
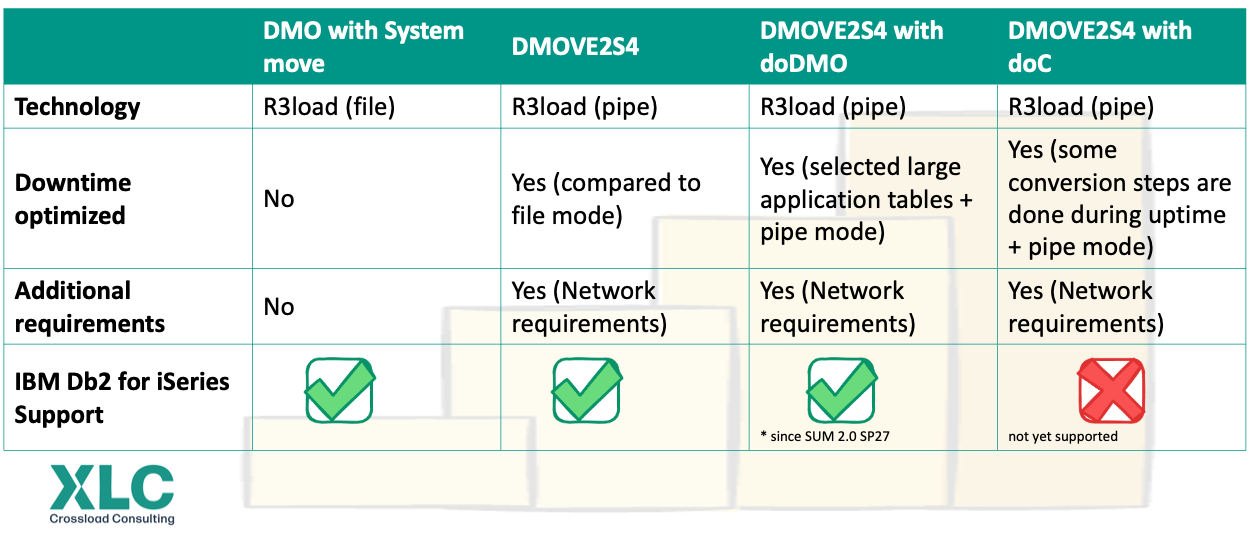
There are multiple DMO scenarios and use cases. We heard of many confusions and mixed up statements which we want to order: SUM can not only update software components, but can also execute a database migration (for ABAP based systems)
DMOVE2S4 and Homogeneous option for SAP SUM DMO
von Jens Gleichmann • 21. Oktober 2026
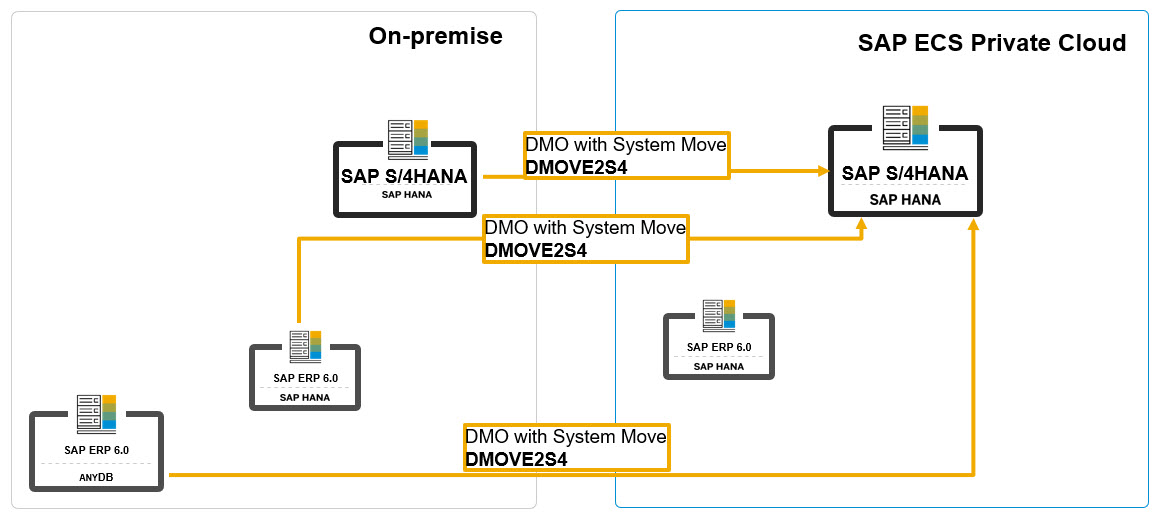
DMO used to be heterogeneous (change of DB). Now you can use DMO with system move (also on-prem to target on-prem) to migrate and convert ECC on HANA to S/4 or just update/upgrade S/4 and move it to another location like other DC or other instance in one step. The DMOVE2S4 is just to move and convert to the cloud in one step. This includes also anyDB source systems and downtime-optimization techniques (doDMO and doC).
von Dominik Fiedler • 7. August 2026
SAP HANA Monitoring Views Cheat Sheet
HANA OS maintenance
von Jens Gleichmann • 27. Juli 2026
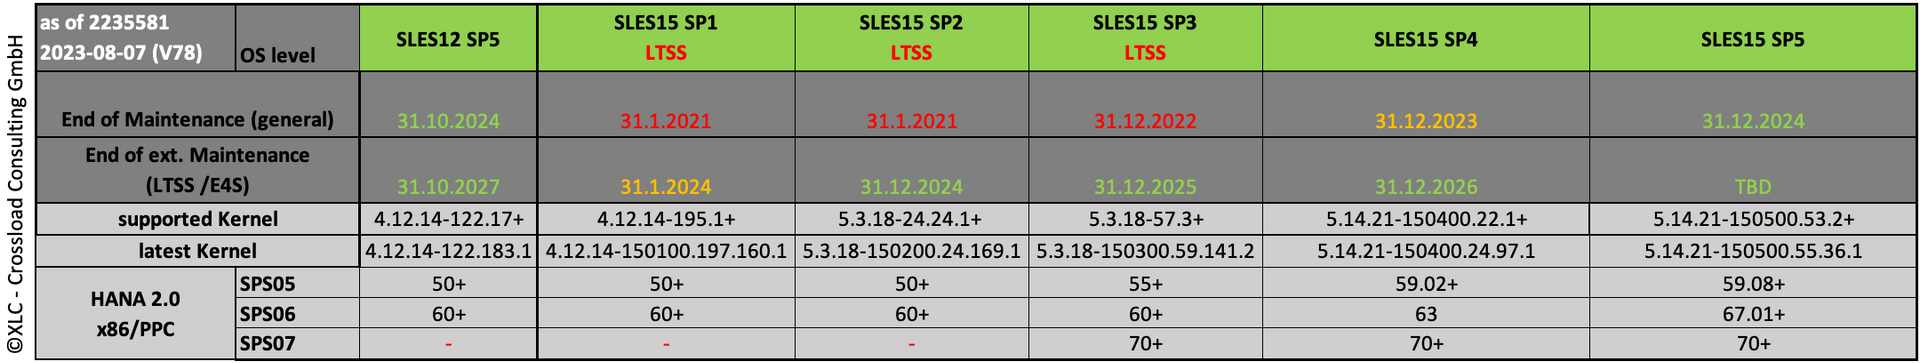
Please notice that when you want to run HANA 2.0 SPS07, you need defined OS levels. As you can see RHEL7 and SLES12 are not certified for SPS07. The SPS07 release of HANA is the basis for the S/4HANA release 2023 which is my recommended go-to release for the next years. Keep in mind that you have to go to SPS07 when you are running SPS06 because it will run out of maintenance end of 2023.
von Jens Gleichmann • 14. April 2026
KVM as alternative with low TCO
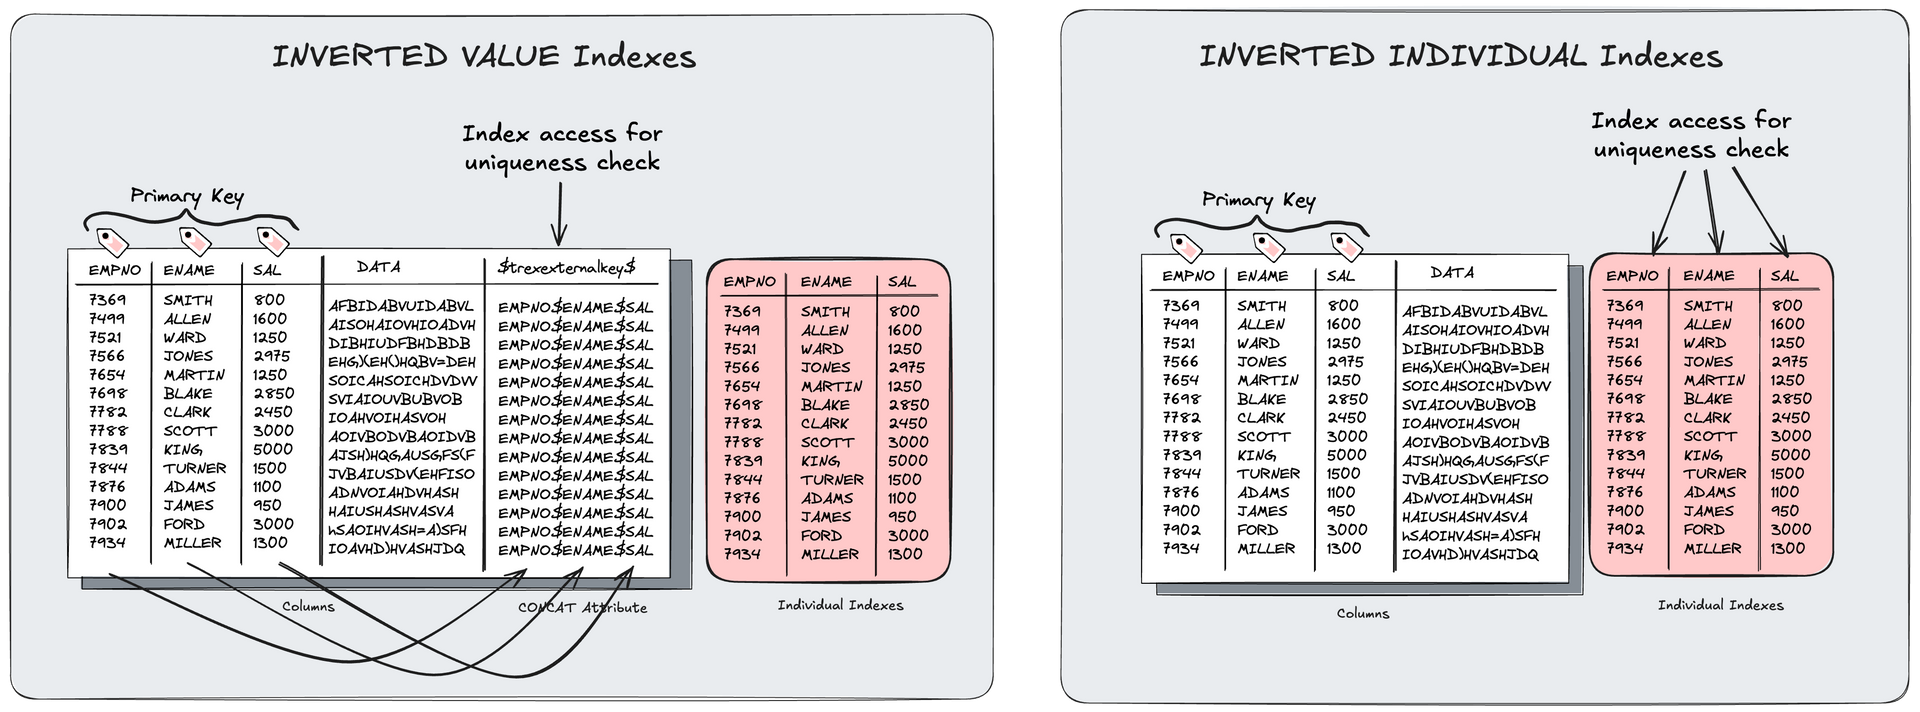
inverted individual index is a special type of SAP HANA index wich can save memory
von Jens Gleichmann • 6. April 2026
An inverted individual index is a special type of SAP HANA index which can only cover unique indexes. This includes all primary key structures. Unlike traditional column store indexes on more than one column (inverted value, inverted hash) an inverted individual index (Inv Idv Idx) doesn't need a dedicated concat.
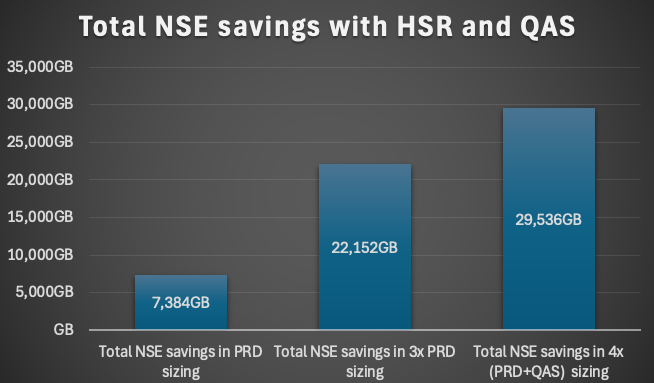
Total NSE savings
von Jens Gleichmann • 5. April 2026
This blog presents the results of a customer case which can be used as a reference for other implementations
SAP HANA performance issues with THP on multi-NUMA node systems
von Jens Gleichmann • 30. März 2026
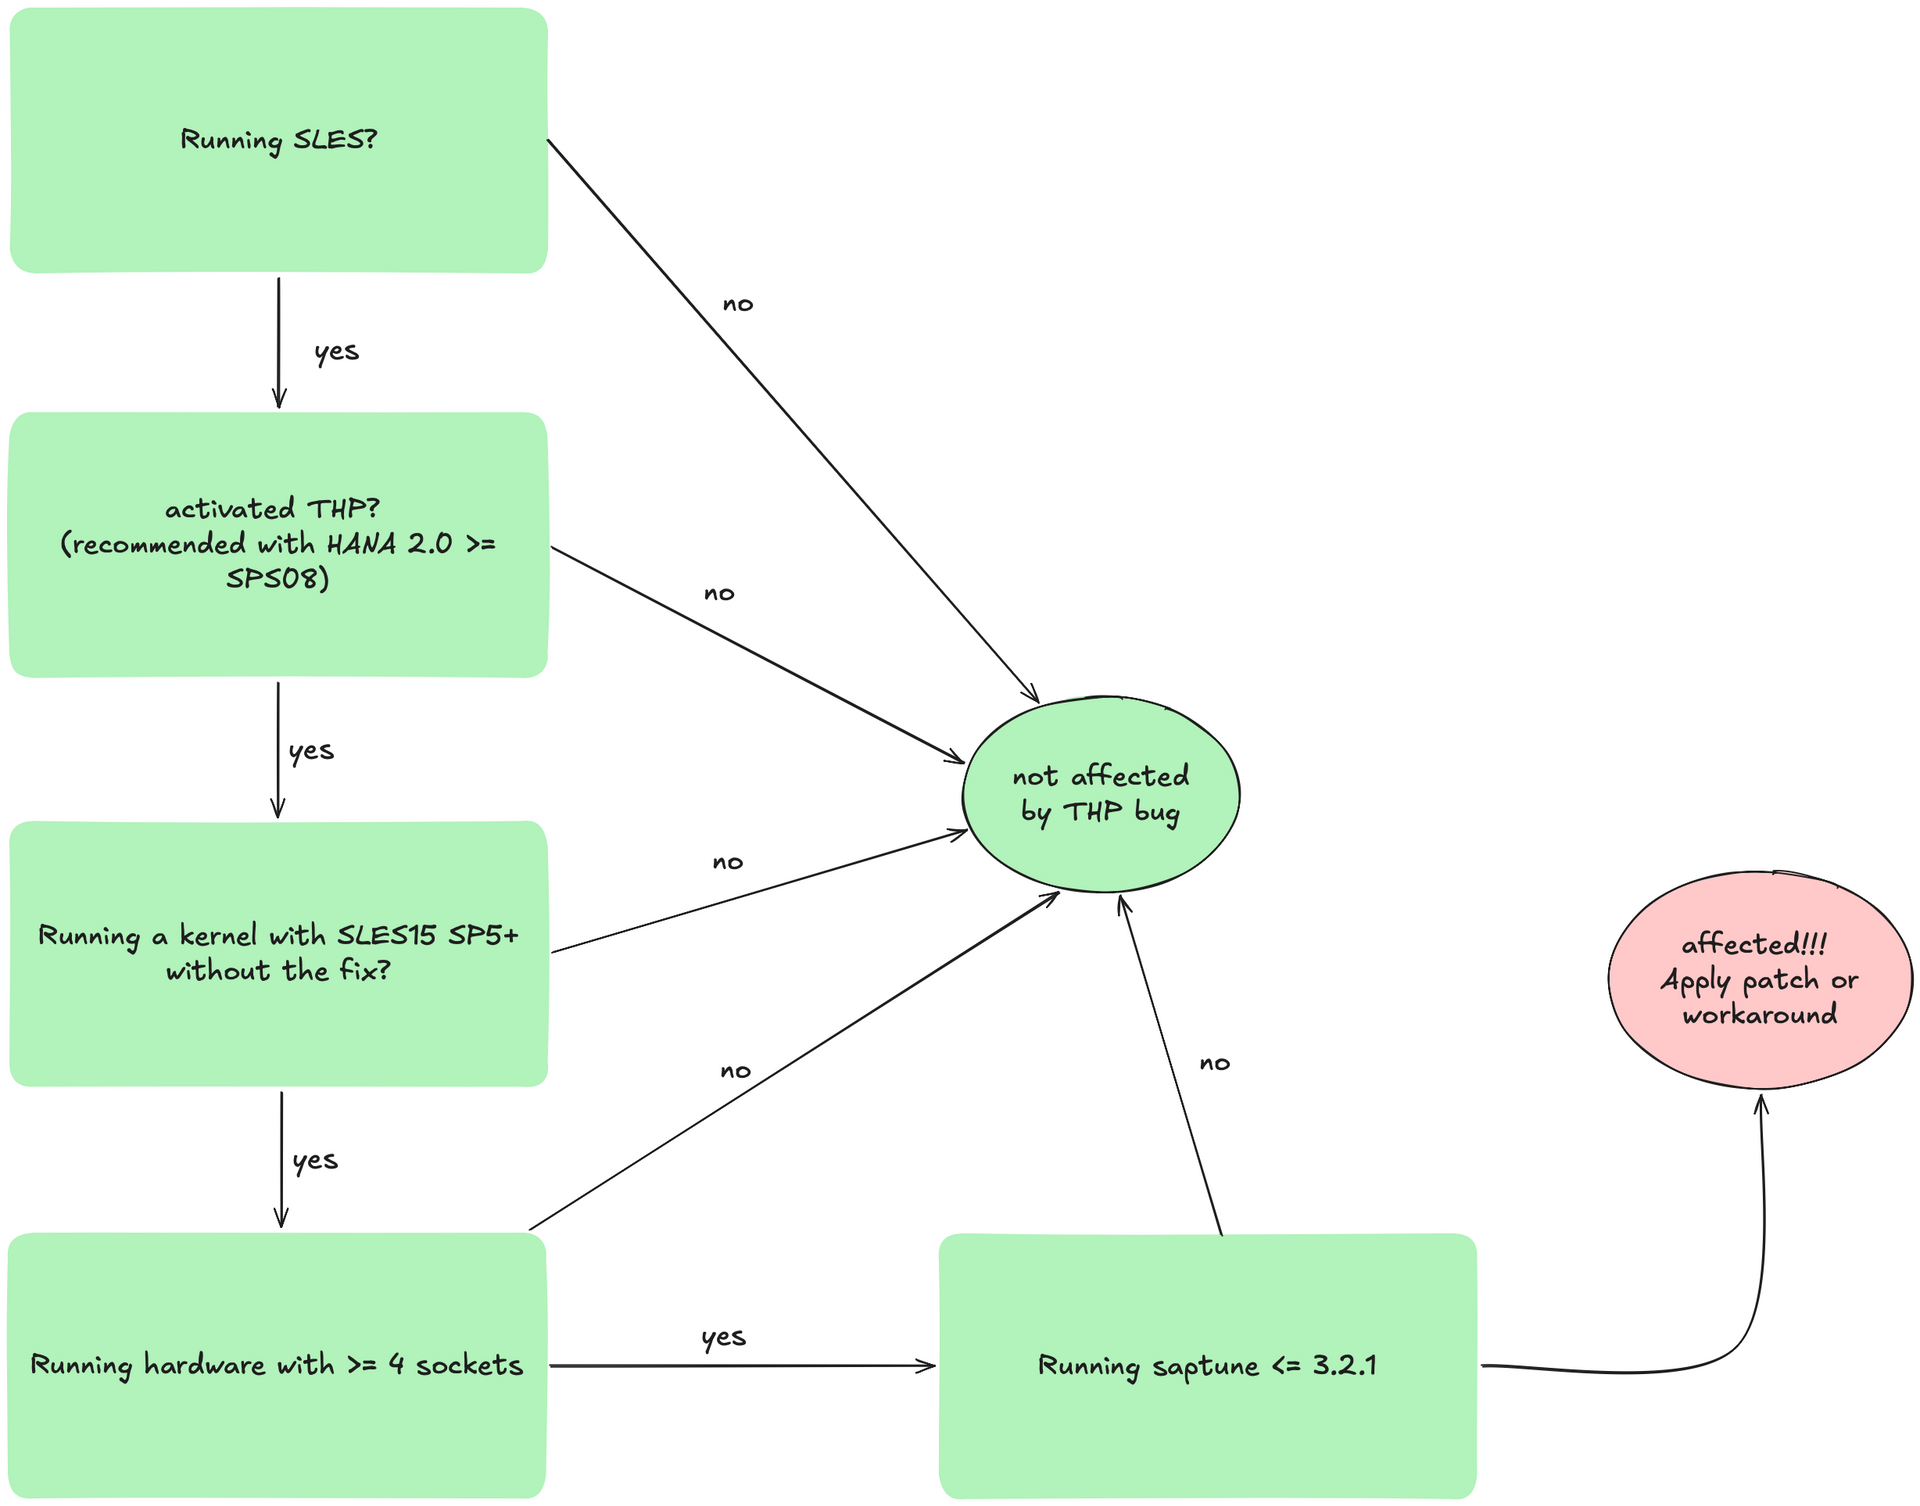
SAP HANA systems may experience high swap usage, hangs, or performance issues when THP (Transparent Huge Pages) is enabled with "madvise". This occurs on multi-NUMA node systems where one or more NUMA nodes are close to full memory usage while others have plenty of free memory, and counters for THP allocations, direct
Transparent Huge Pages (THP) with madvise can trigger high swap usage and performance issues
von Matthias Sander • 26. Januar 2026
Transparent Huge Pages (THP) with madvise can trigger high swap usage, performance issues, or even system hangs on multi-NUMA systems.
more